Inferring 1-Minimal Trigger Configurations for Assessing Linux Kernel CVE Triggerability
Infers Kconfig-satisfiable, 1-minimal configurations for assessing whether Linux kernel CVEs can be triggered, with runtime validation.
Intelligent software engineering
Associate Professor · Shandong Normal University
School of Computer Science and Artificial Intelligence
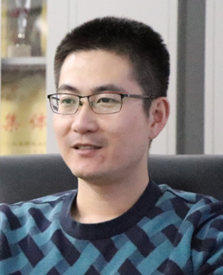
I work on intelligent software engineering, with three connected research interests: trustworthy code generation, Program comprehension, and software security. My group studies semantic and structural representations of programs, code summarization, correct and efficient code generation, and auditable generation pipelines. We also investigate repository-level vulnerability analysis and the security of code language models.
CorrectnessEfficiencySecurityAuditability
Recent updates
Our FCC artifact has been selected for the ISSTA 2026 Distinguished Artifact Award.
FCC accepted to ISSTA 2026. Congratulations to Tongjie!
EffiSkel accepted to FSE 2026. Congratulations to Yuyu!
Serving on the Program Committee of ASE 2026.
SemGuard accepted to ASE 2025. Congratulations to Qinglin!
Invited talk at Huawei 2012 Lab, Compiler & Programming Languages Lab, Shanghai: “New explorations in optimizing code recommendation models.”
Invited talk at ChinaSoft, Intelligent Software Development, Testing & Maintenance Forum: “Complex Code Generation: Strategies for Improving Model Performance.”
RankEF accepted to ASE 2024. Congratulations to Zhihong!
KareCoder accepted to ICSE 2024 Posters. Congratulations to Tao Huang!
IRCoCo accepted to FSE 2024. Congratulations to Bolun!
Questions and directions
How can code models produce correct, efficient, and secure programs — while making their decisions auditable? We study semantic guidance, execution-informed ranking, structured supervision, and explicit evidence in the generation process.
Efficiency: measurement, models, and alignment
Our efficiency work spans benchmarks, specialized models, and structure-guided learning.
How can models capture program structure and semantics, and explain what code does? We study tree-aware pretraining, hierarchical representation learning, and fine-grained fusion of code features for Program comprehension and natural-language code summaries.
Repository-level code security
How can we detect vulnerabilities and establish when they can actually be triggered? We investigate repository-level analysis, reproducible vulnerability assessment, and LLM-assisted CodeQL rule generation, repair, and evaluation.
Security of code language models
How can code models remain reliable under adversarial inputs? Our interests include prompt-injection and jailbreak defenses, poisoning robustness, risk assessment, and guardrails for code generation.
We also study deep architectures and their deployment in low-level vision, including Transformer, Mamba, and KAN models for super-resolution, denoising, and dehazing. See selected publications in vision and signal processing.
Other technical interests include low-memory code generation, safety-aware and constrained decoding, rollback, candidate ranking, efficiency/security evaluation, and evidence chains; joint coverage and quality metrics for CodeQL benchmarks; adversarial examples, exploit-chain risk assessment, red/blue teaming, and policy-compliant output filtering.
From explainable to auditable code — guided by rules, measured by evidence.
不以规矩,不能成方圆
* Corresponding author. Earlier entries use the published name Chen Lv. Journal entries use the volume year.
Software-engineering work is listed first, followed by selected work in vision & signal processing. Filters search both groups.
Software engineering
Infers Kconfig-satisfiable, 1-minimal configurations for assessing whether Linux kernel CVEs can be triggered, with runtime validation.
Uses structured skeleton supervision to help code models learn efficient implementations.
Uses code skeletons to guide preference optimization toward efficient code generation.
Detects semantic deviations during code generation and guides corrective regeneration.
Empirically evaluates ensembles of large language models for code vulnerability detection.
A benchmark of 95,359 efficient–inefficient code pairs, with metrics for evaluating code-efficiency optimization.
Combines pretrained models with an expert encoder group to represent different input types for efficient code generation.
Learns from execution feedback to rank generated code candidates.
Uses immediate rewards in reinforcement learning to guide code completion.
Introduces KareCoder, using algorithm and data-structure knowledge to support code generation on unfamiliar programming problems.
Incorporates programming knowledge into a code generation system.
Distills LLM reasoning into smaller code models through solution plans and joint plan-and-code generation.
A dataset for algorithmic code generation, organized by topics, algorithms, skills, and difficulty.
Enriches abstract syntax trees with data-flow and control-flow information for multi-modal source code summarization.
Introduces GEC for measuring the efficiency of generated code.
Combines multi-scale AST features and source-code tokens with cross-modal fusion for code summarization.
Aligns and fuses fine-grained features across code modalities to generate natural-language summaries.
Learns hierarchical code representations from ASTs using contrastive learning for classification, clone detection, and clustering.
Combines local API dependency graphs with AST features using similarity-guided fusion for code summarization.
A tree-aware pretrained model that uses AST paths and structure-sensitive objectives for code summarization and documentation.
Combines API dependency graph embeddings with sequence-to-sequence generation to represent global relationships among API methods.
Beyond software engineering
Selected journal articles on ultra-high-definition image restoration and video summarization.
Uses dimensional transformation and multi-scale features for dehazing ultra-high-definition industrial images.
Uses an interpretable pyramid network to restore ultra-high-definition hazy images.
Uses adaptive multiview graph differences and shot-boundary analysis to produce video summaries.
No publications match these filters.
Code, data, and artifacts
Implementation
Code and supporting resources for semantic guidance during code generation.
Explore the codeDataset
Algorithmic programming tasks with structured topic and difficulty information.
Explore the dataResearch artifact
Reproduction package for assessing Linux kernel CVE triggerability.
View the artifactEfficiency benchmark
Efficient–inefficient code pairs and evaluation resources for code-efficiency optimization.
Explore code & dataSelected activities
Program Committee, ASE 2026.
Invited talk, Huawei 2012 Lab, Compiler & Programming Languages Lab, Shanghai.
“New explorations in optimizing code recommendation models.”
Invited talk, ChinaSoft, Intelligent Software Development, Testing & Maintenance Forum.
“Complex Code Generation: Strategies for Improving Model Performance.”
Students and collaborators
I welcome motivated students and collaborators interested in code generation, Program comprehension and code summarization, and software security — including repository-level analysis and the security of code language models.
Please include a brief introduction and the research question or project you would like to discuss.